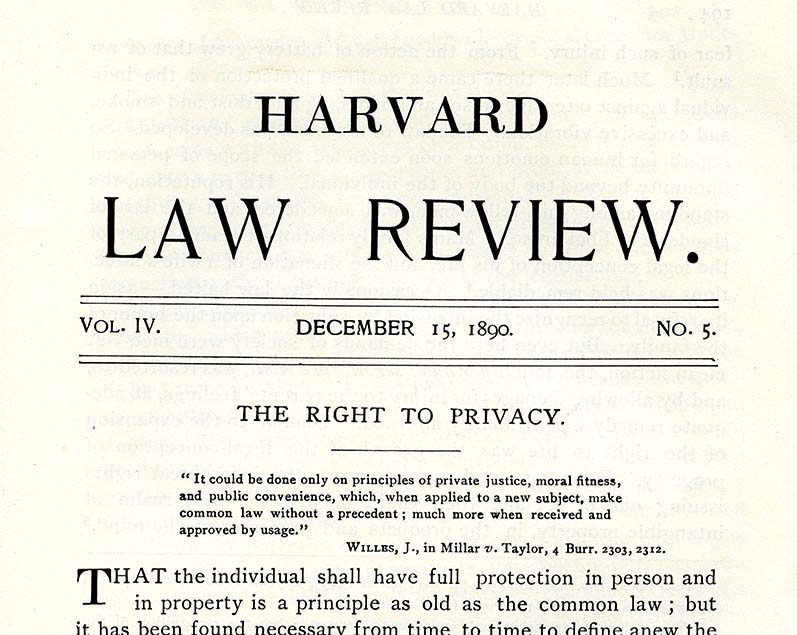
Louis Brandeis, along with his law partner Samuel Warren, penned “The Right to Privacy” in 1890, marking a pivotal moment in the discourse on privacy rights. The article articulated a valid argument for the recognition of a fundamental right to privacy in American jurisprudence, which still influences the debates we have had today about the intersection of privacy law and emerging technology such as AI, surveillance, and the internet.
Defining Privacy Rights
In “The Right to Privacy”, Brandeis and Warren framed privacy as the right to be left alone, a notion plenty of people can relate to especially if you are living in the social media age. Essentially being left alone meant shielding individuals from unwarranted intrusion into their personal lives, thoughts, and affairs. They identified two types of privacy invasions: the use of one’s likeness or personal information for commercial purposes without consent, and the publication of private information that could cause emotional distress or harm to one’s reputation.
Brandeis and Warren highlighted the detrimental effects of sensationalist journalism and emerging technologies such as photography on individual privacy. They argued that advances in technology had outpaced legal protections, leaving individuals vulnerable to intrusive media practices and public exposure without a proper remedy to collect on. In hind sight they essentially predicted the world we live in now, one full of Tik Toks, selfies, streamers, and retweets.
Individual Autonomy and Dignity
The core focus of the article was advocacy for privacy rights which reflected broader philosophical principles of individual autonomy, dignity, and the right to control one’s personal information and identity. The article emphasized the importance of privacy in preserving personal autonomy, fostering intimate relationships, and cultivating individuality free from external scrutiny and interference.
Brandeis’ philosophical stance resonated with Enlightenment ideals of personal liberty and dignity that were popular with thinkers at the time, challenging the notion that individuals should be subject to public scrutiny or commodification without their consent. His advocacy for privacy rights aligned with a broader movement towards recognizing and protecting individual rights against encroachment by powerful societal forces, whether governmental, corporate, or media related.
Influence on American Jurisprudence
“The Right to Privacy” had a profound impact on American jurisprudence, laying the groundwork for the development of privacy law in the United States. Though not immediately codified into statutory law, Brandeis’ and Warren’s ideas influenced judicial interpretations and legislative efforts to protect privacy rights in various contexts.
The article set forth a conceptual framework for recognizing privacy as an inherent and fundamental right implicit in the U.S. Constitution, particularly in the Fourth Amendment’s protections against unreasonable searches and seizures. Brandeis’ arguments resonated in subsequent Supreme Court decisions, including Olmstead v. United States (1928) and Griswold v. Connecticut (1965), which recognized privacy rights in the context of wiretapping and contraception.
Brandeis’ philosophical and legal legacy continues to inform contemporary debates on privacy rights in the digital age, as technology continues to reshape how personal information is collected, stored, and disseminated. His advocacy for privacy as a bulwark against invasive technologies and media practices remains relevant as society grapples with issues of data privacy, cybersecurity, and surveillance in the 21st century. So though the article was written in the 19th century, it would be able to tackle the core privacy issues new technology such as the internet would pose.
Early Foundations of Cyber Law
The early development of cyber law in the United States was influenced by a series of legislative initiatives aimed at addressing the challenges posed by digital communication, electronic commerce, and data privacy. This further entrenched the idea Brandeis and Warren had one hundred years prior, privacy must be safeguarded. One of the earliest legislative efforts was the Electronic Communications Privacy Act (ECPA) of 1986, which established protections against unauthorized interception of electronic communications and access to stored electronic communications. The ECPA safeguarded digital privacy rights, setting the stage for subsequent legislative and judicial developments. It was clear Warren and Brandeis’ message had reached the law makers tackling the privacy issues this new technology was posing.
Another pivotal piece of legislation was the Computer Fraud and Abuse Act (CFAA) of 1986, which criminalized unauthorized access to computer systems and provided civil remedies for victims of computer related crimes. The CFAA was instrumental in addressing cybersecurity threats and unauthorized access to sensitive information, establishing a legal framework for prosecuting cybercrime and protecting the integrity of a user’s private digital systems(computers, phones, usb etc).
Privacy Law in Healthcare
The most commonly cited piece of privacy legislation is HIPPA, ( The Health Insurance Portability and Accountability Act) which introduced comprehensive standards for protecting personal health information and electronic health records. HIPAA’s Privacy Rule and Security Rule established guidelines for healthcare providers, insurers, and business associates to ensure the confidentiality, integrity, and availability of Protected Health Information (PHI). The enactment of HIPAA represented a significant advancement in healthcare privacy law. As well as emphasizing the importance of protecting sensitive medical information, further expanding on the notions of private sensitive information that the Brandeis article discussed.
HIPAA truly transformed the US standard on handling medical information. It serves as a robust shield protecting personal health details from unauthorized access and ensuring stringent confidentiality standards. Before HIPAA, the landscape was less regulated, regular people had valid concerns over who could access medical records and their security. HIPAA’s impact extends beyond privacy it fortifies defenses against cyber threats, ensuring medical data remains secure.
Privacy in the Digital Age: Challenges and Regulatory Responses
However, though there have been strides in privacy regulation, there have still been issues that have not been adequately addressed. For example, the proliferation of digital communication, social media platforms, and online commerce has raised new challenges for privacy law, prompting regulatory responses to address issues such as data breaches, online tracking, and consumer profiling. The Federal Trade Commission (FTC) has played a central role in enforcing consumer privacy protections under its authority to prevent unfair and deceptive practices in commerce. The FTC’s enforcement actions have targeted companies that fail to secure consumer data, engage in deceptive data collection practices, or violate consumers’ privacy preferences.
However, critics have argued that the FTC alone cannot enforce every possible violation at the federal level, and that some state intervention is also needed. In recent years, concerns about online privacy have been amplified by high profile data breaches and scandals involving major technology companies. The Cambridge Analytica scandal, in which Facebook users’ personal data was harvested for political purposes without their consent, underscored the vulnerability of personal information in the digital age and sparked public debate about the need for stronger privacy protections. And now some state’s have responded with their own protections.
State Level Regulation
Illinois’s Biometric Information Privacy Act (BIPA)
The Biometric Information Privacy Act (BIPA) was passed in 2008 by Illinois’s legislature and is one of the most stringent biometric privacy laws in the United States. The act is aimed at regulating the collection, storage, use, and dissemination of biometric identifiers and biometric information. Biometric identifiers covered under BIPA include fingerprints, retina or iris scans, voiceprints, and facial geometry scans.
BIPA mandates that private entities obtain informed consent from individuals before collecting their biometric identifiers or information. Entities must disclose the specific purpose and duration for which biometric data is being collected, stored, and used.
Additionally it imposes strict guidelines on the retention and destruction of biometric data. Entities must establish a written policy outlining the retention schedule and guidelines for permanently destroying biometric information once the purpose for its collection has been fulfilled or after a certain period expires.
BIPA prohibits private entities from selling, leasing, trading, or otherwise profiting from an individual’s biometric identifiers or information. Entities are also prohibited from disclosing biometric data without obtaining the individual’s consent or as required by law.
One of the most notable aspects of BIPA is its provision allowing individuals to sue private entities for violations of the statute. Individuals can seek damages ranging from $1,000 for negligent violations to $5,000 for intentional or reckless violations, as well as attorney’s fees and costs.
The private right of action under BIPA has led to a significant number of class action lawsuits against companies alleged to have violated the statute’s provisions. These lawsuits have underscored the importance of compliance with BIPA’s requirements and the potential financial liabilities for noncompliance.
In the case of Patel v. Facebook, filed in Illinois in 2015, users accused Facebook of unlawfully collecting and storing biometric data through its “Tag Suggestions” feature. This feature automatically recognized and suggested tags for people in photos uploaded to Facebook based on facial recognition technology, without explicit consent from users. Plaintiffs argued that Facebook’s practices violated BIPA by failing to inform users about the collection and use of their biometric data and obtain their written consent.
The lawsuit proceeded as a class action, representing millions of Illinois Facebook users affected by the alleged violations of BIPA. Over the course of litigation, Facebook contested the lawsuit’s class certification and challenged the interpretation of BIPA’s requirements.
Ultimately, in 2020, Facebook agreed to settle the Patel lawsuit for $650 million, one of the largest settlements in history for a privacy related lawsuit. The settlement underscored the substantial financial risks companies face for non compliance with biometric privacy laws like BIPA and reinforced the importance of obtaining informed consent and implementing robust data protection measures in biometric technology.
The California Consumer Privacy Act
The California Consumer Privacy Act (CCPA) of 2018 grants consumers rights to access, delete, and opt out of the sale of their personal information, reflecting a state level effort to strengthen privacy rights and regulate data driven business practices. This law was heavily influenced by European Union legislation that broadly protects data privacy for all EU member countries.
Global Influence: GDPR and Setting Privacy Standards
One of the gold standards for data specific privacy regulation is The European Union’s General Data Protection Regulation (GDPR), implemented in 2018. It has had a transformative impact on global privacy standards by establishing comprehensive requirements for data protection, user consent, and individual rights over personal data. The GDPR’s principles of transparency, accountability, and data minimization have set a global benchmark for privacy regulation, influencing regulatory frameworks and corporate practices worldwide.
Any policymaker knows that drafting and passing a statute is half the battle, proper enforcement is what actually influences law. The GDPR incentivizes proper enforcement. Its enforcement is effective because the statute combines substantial financial penalties, strong regulatory authority, and enumerates clearly defined individual rights. The possibility of significant fines creates a real economic incentive for companies to comply, while regulators can investigate violations and require corrective action. This combination makes privacy obligations enforceable rather than merely aspirational, encouraging organizations to build data protection into their everyday operations and corporate decision making.
Emerging Technologies and Privacy Challenges: AI, Biometrics, and Surveillance
The rapid advancement of emerging technologies such as artificial intelligence (AI), biometric data collection, and facial recognition has raised complex legal and ethical questions about privacy rights and surveillance in the digital age. AI algorithms capable of processing vast amounts of personal data for predictive analytics and decision making purposes have prompted calls for consumer regulatory oversight to ensure that AI systems respect privacy rights, avoid bias, and uphold transparency.
The use of biometric identifiers such as fingerprints, iris scans, and facial images for authentication and identification purposes has introduced new challenges for privacy law, as biometric data is inherently sensitive and permanent.
Surveillance technologies, including local police and corporate surveillance programs, pose additional challenges to privacy rights and civil liberties. The debate over mass surveillance, warrantless wiretapping, and the collection of metadata has prompted legal challenges and legislative efforts to strike a balance between national security interests and individual privacy rights. This is evident in the recent discourse in various American states surrounding Flock cameras and how the technology can be misused by local police departments.
The Future of Cyber Law and Privacy: Adapting to Technological Change
Looking ahead, the evolution of cyber law and privacy in the United States will continue to be shaped by rapid technological advancement but it is imperative to balance innovation with robust regulatory oversight. Policymakers, legal scholars, and industry stakeholders must collaborate to develop adaptive legal frameworks that protect privacy rights, promote technological innovation, national security, and maintain public trust in digital technologies.
Efforts to establish ethical guidelines and regulatory frameworks for emerging technologies like AI, blockchain, and the internet as a whole will be essential in addressing privacy challenges and ensuring that technological innovations benefit society while respecting individual rights. Principles of accountability, transparency, and fairness will guide regulatory efforts to mitigate risks associated with data privacy, cybersecurity threats, and the ethical implications of AI and machine learning.
It is clear that Louis Brandeis’ article “The Right to Privacy” remains a foundational text in the evolution of privacy law and ethics, articulating enduring principles of individual autonomy and the right to be free from unwarranted intrusion. These philosophical insights helped outline the arguments on the importance of privacy rights which continue to guide legal frameworks and policy debates, shaping how societies balance technological innovation with the protection of fundamental human rights.
As the United States and other nations navigate the complexities of the digital age, the commitment to upholding privacy rights must remain focused, grounded in Brandeis’ vision of a society where individuals can assert control over their personal information and maintain autonomy in an increasingly interconnected world.
Sources
-Brandeis, Louis D., and Samuel D. Warren. “The Right to Privacy.”
-California Consumer Privacy Act of 2018. Cal. Civ. Code §§ 1798.100–1798.199.
-Computer Fraud and Abuse Act of 1986. 18 U.S.C. § 1030.
-Electronic Communications Privacy Act of 1986. 18 U.S.C. §§ 2510–2523, 2701–2713, 3121–3127.
-European Parliament and Council of the European Union. “Regulation (EU) 2016/679 (General Data Protection Regulation).” Official Journal of the European Union, 2016.
-Health Insurance Portability and Accountability Act of 1996. Pub. L. No. 104-191, 110 Stat. 1936.
-Illinois Biometric Information Privacy Act. 740 Ill. Comp. Stat. 14/1–14/99.
–Olmstead v. United States. 277 U.S. 438. Supreme Court of the United States, 1928.
–Patel v. Facebook, Inc. 932 F.3d 1264. United States Court of Appeals for the Ninth Circuit, 2019.
–Griswold v. Connecticut. 381 U.S. 479. Supreme Court of the United States, 1965.